Abstract
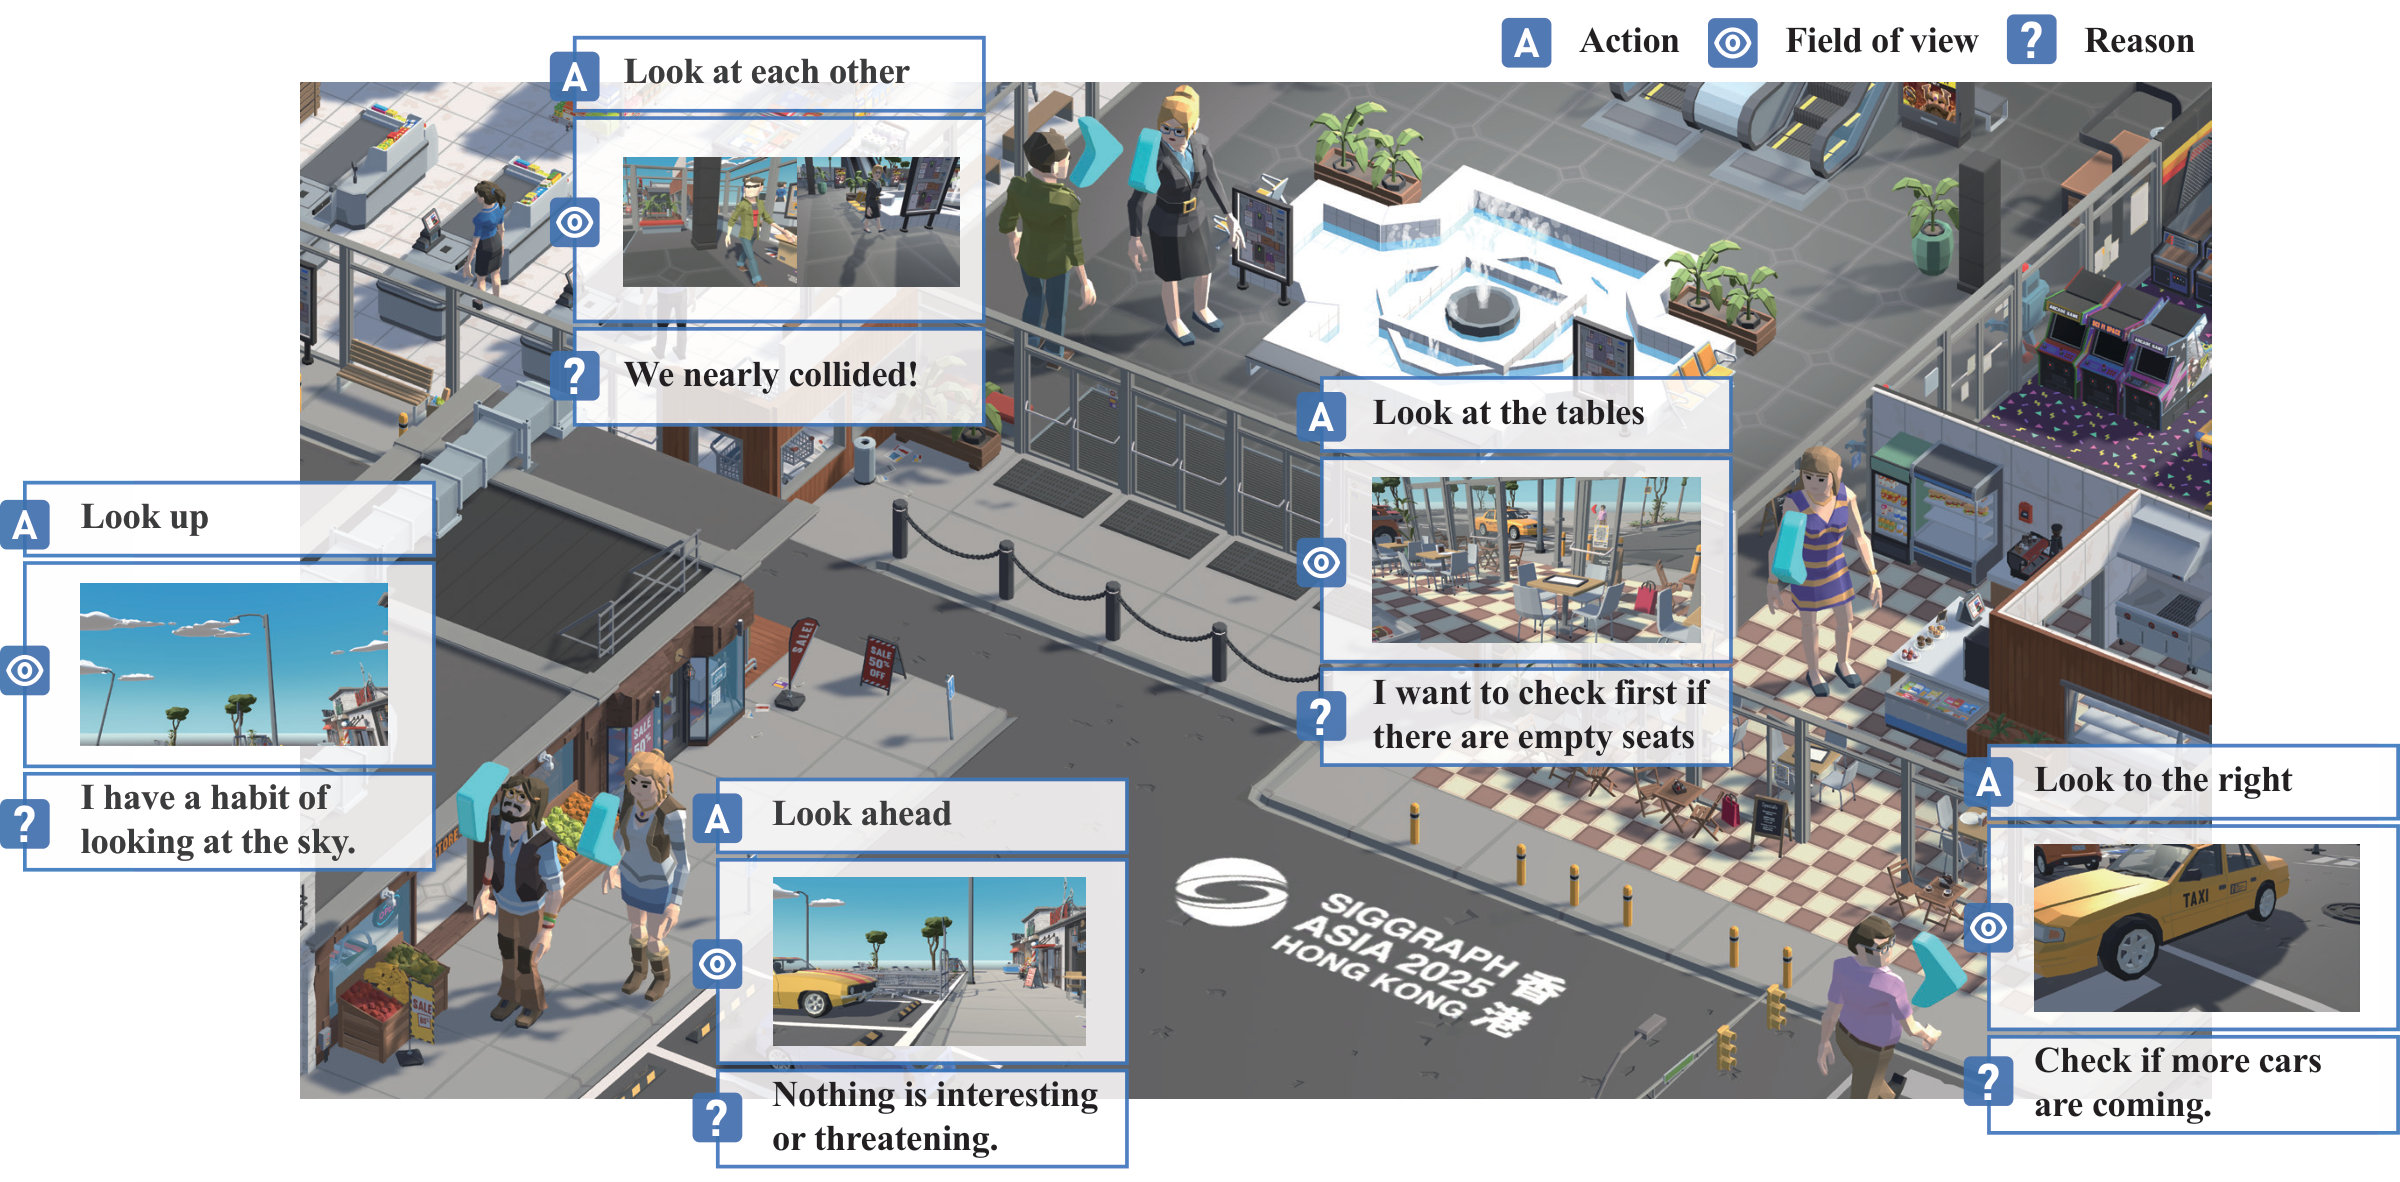
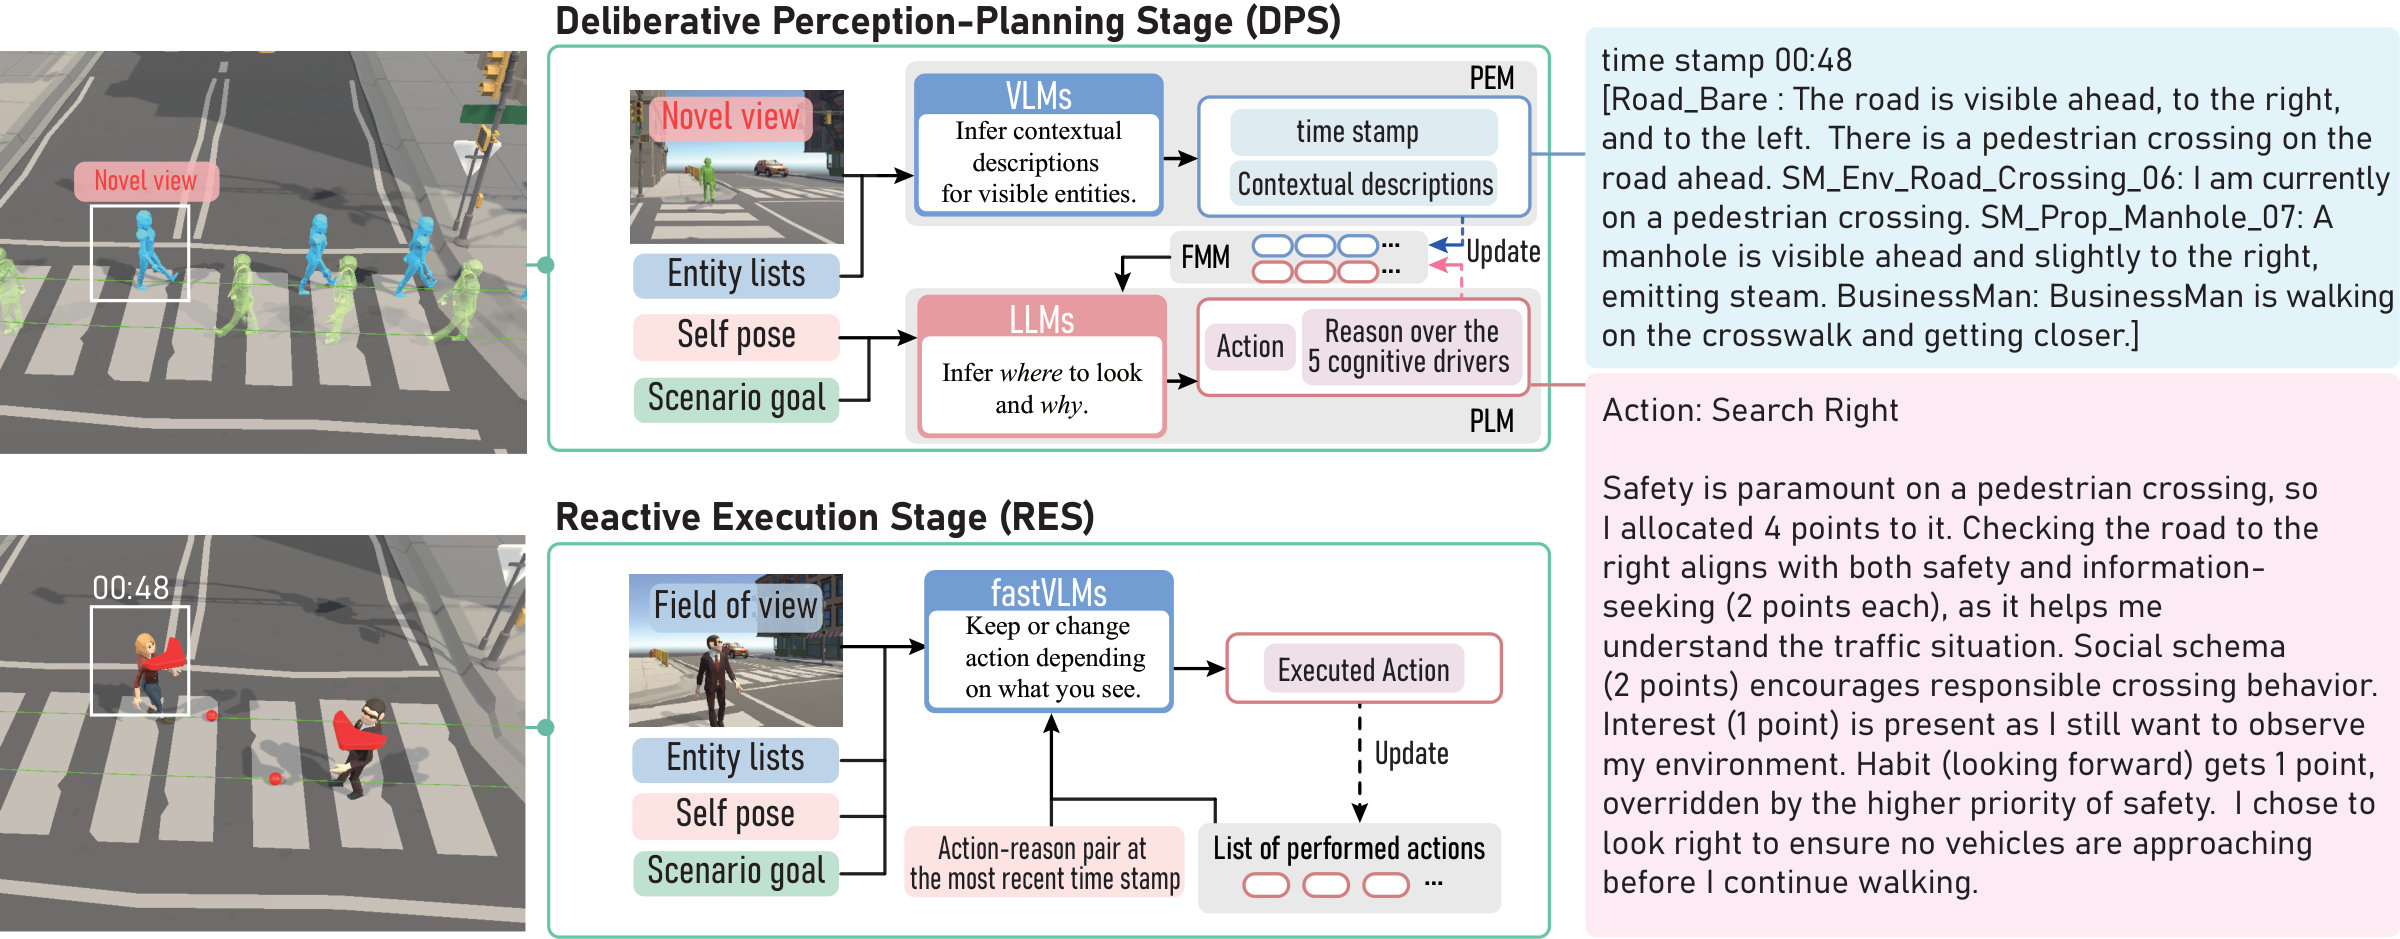
Natural head rotation is critical for believable embodied virtual agents, yet this micro-level behavior remains largely underexplored. While head-rotation prediction algorithms could, in principle, reproduce this behavior, they typically focus on visually salient stimuli and overlook the cognitive motives that guide head rotation. This yields agents that look at conspicuous objects while overlooking obstacles or task-relevant cues, diminishing realism in a virtual environment. We introduce SCORE, a Symbolic COgnitive Reasoning framework for Embodied Head Rotation, a data-agnostic framework that produces context-aware head movements without task-specific training or hand-tuned heuristics. A controlled VR study (N=20) identifies five motivational drivers of human head movements: Interest, Information Seeking, Safety, Social Schema, and Habit. SCORE encodes these drivers as symbolic predicates, perceives the scene with a Vision–Language Model (VLM), and plans head poses with a Large Language Model (LLM). The framework employs a hybrid workflow: the VLM–LLM reasoning is executed offline, after which a lightweight FastVLM performs online validation to suppress hallucinations while maintaining responsiveness to scene dynamics. The result is an agent that predicts not only where to look but also why, generalizing to unseen scenes and multi-agent crowds while retaining behavioral plausibility.
Video
User Study
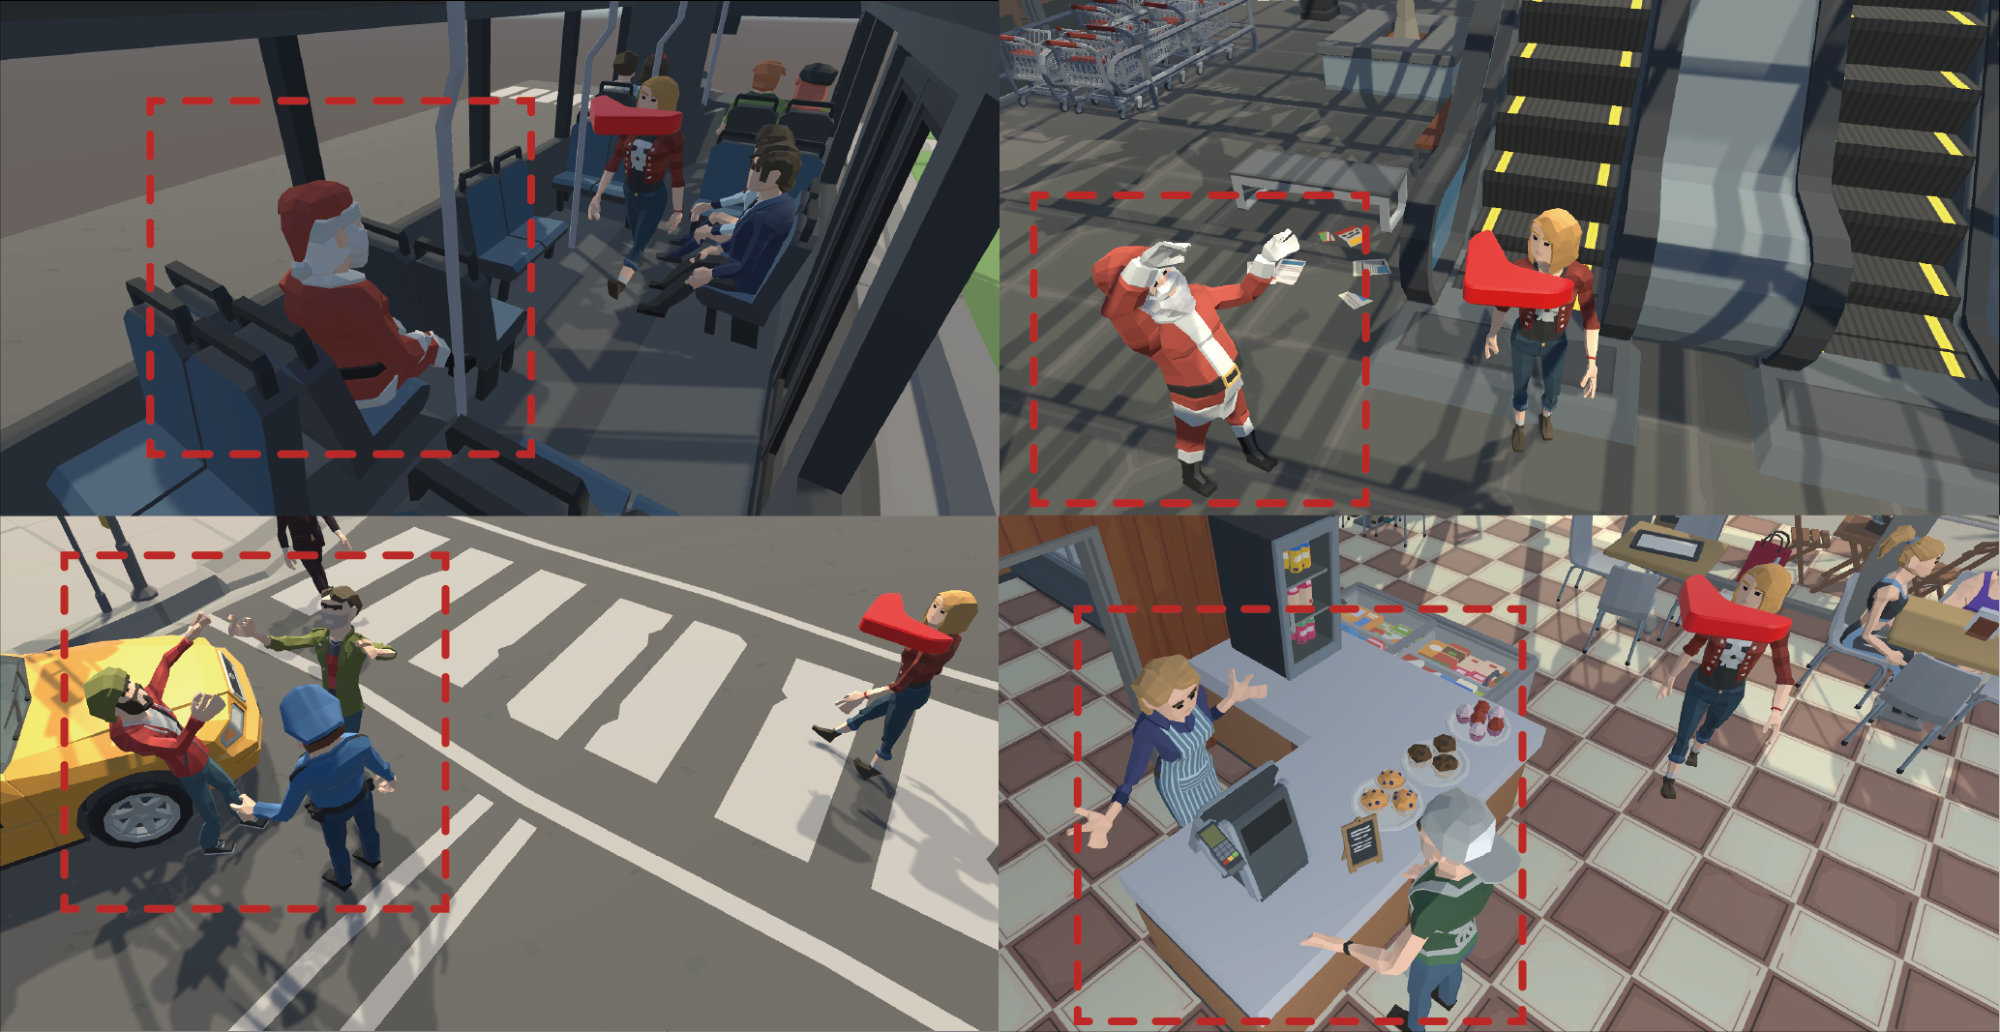
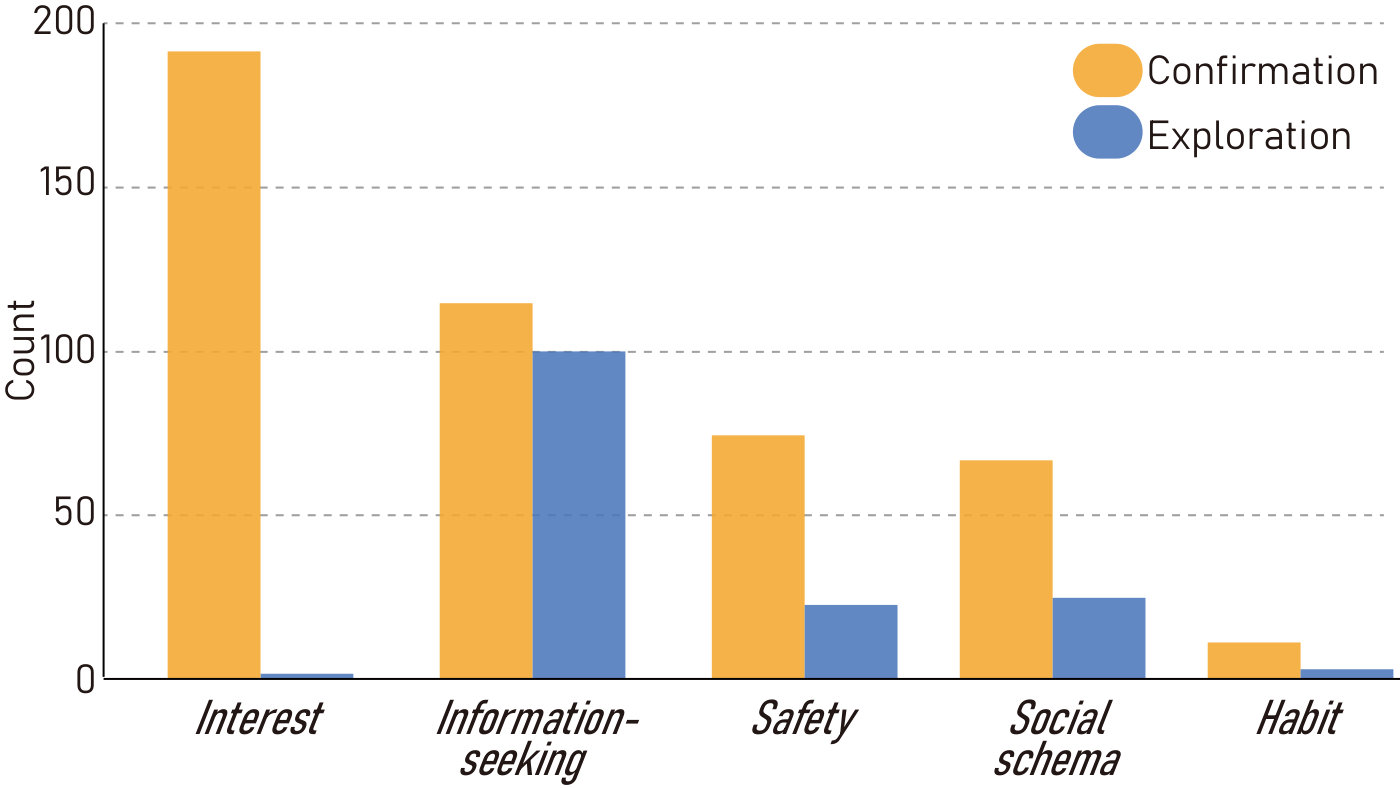
Interest
Information seeking
Safety
Social schema
Habit
Method
Interactive Replay
Recorded head trajectories of SCORE, VR participants (Human) and the saliency baseline Track.
Head-Rotation Trajectories
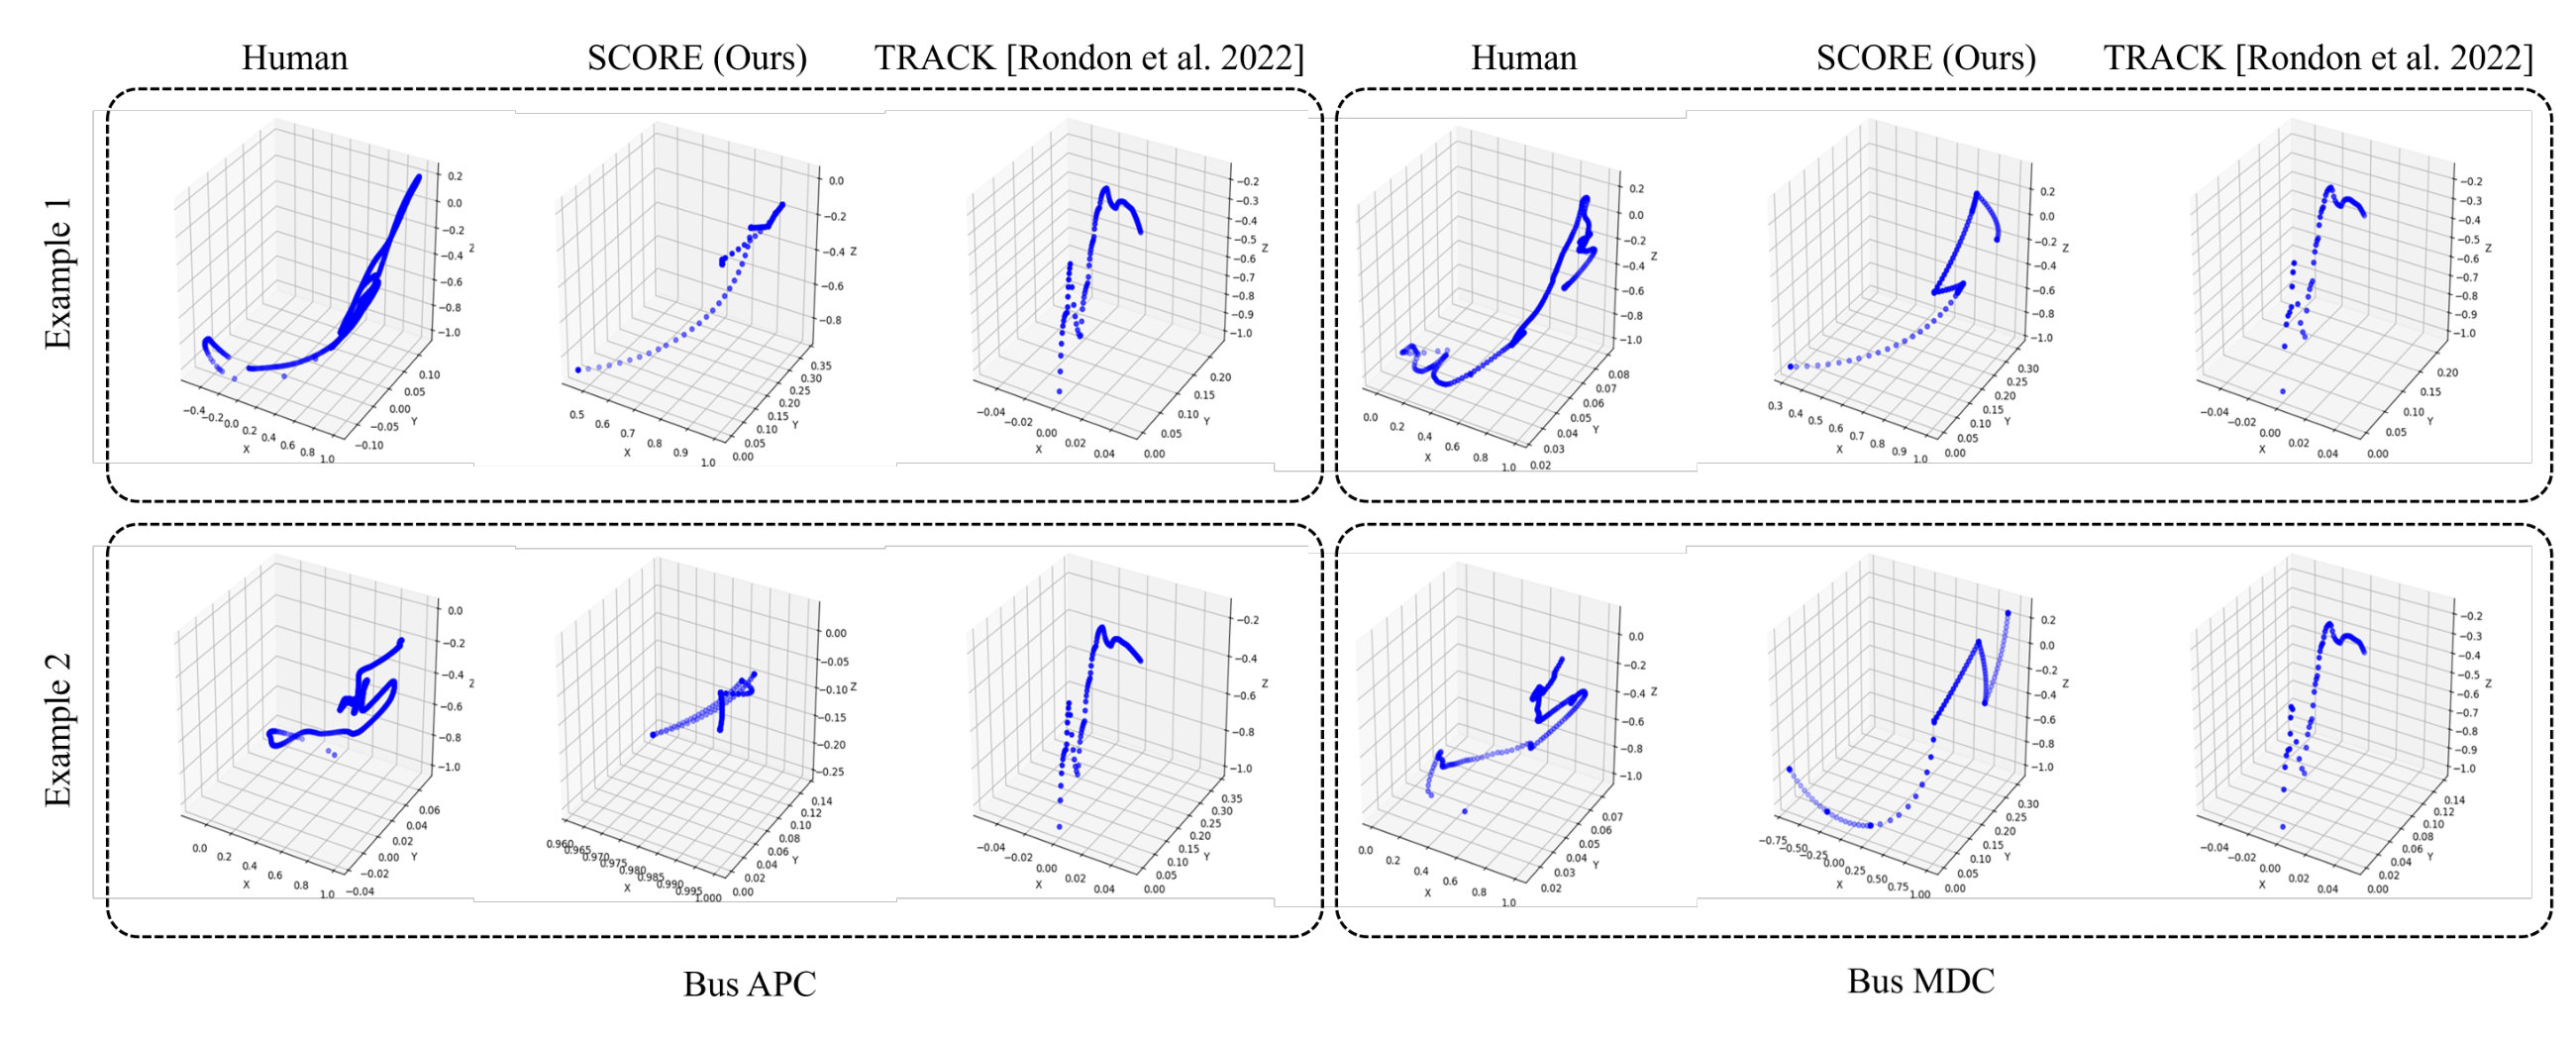
Rotate it yourself
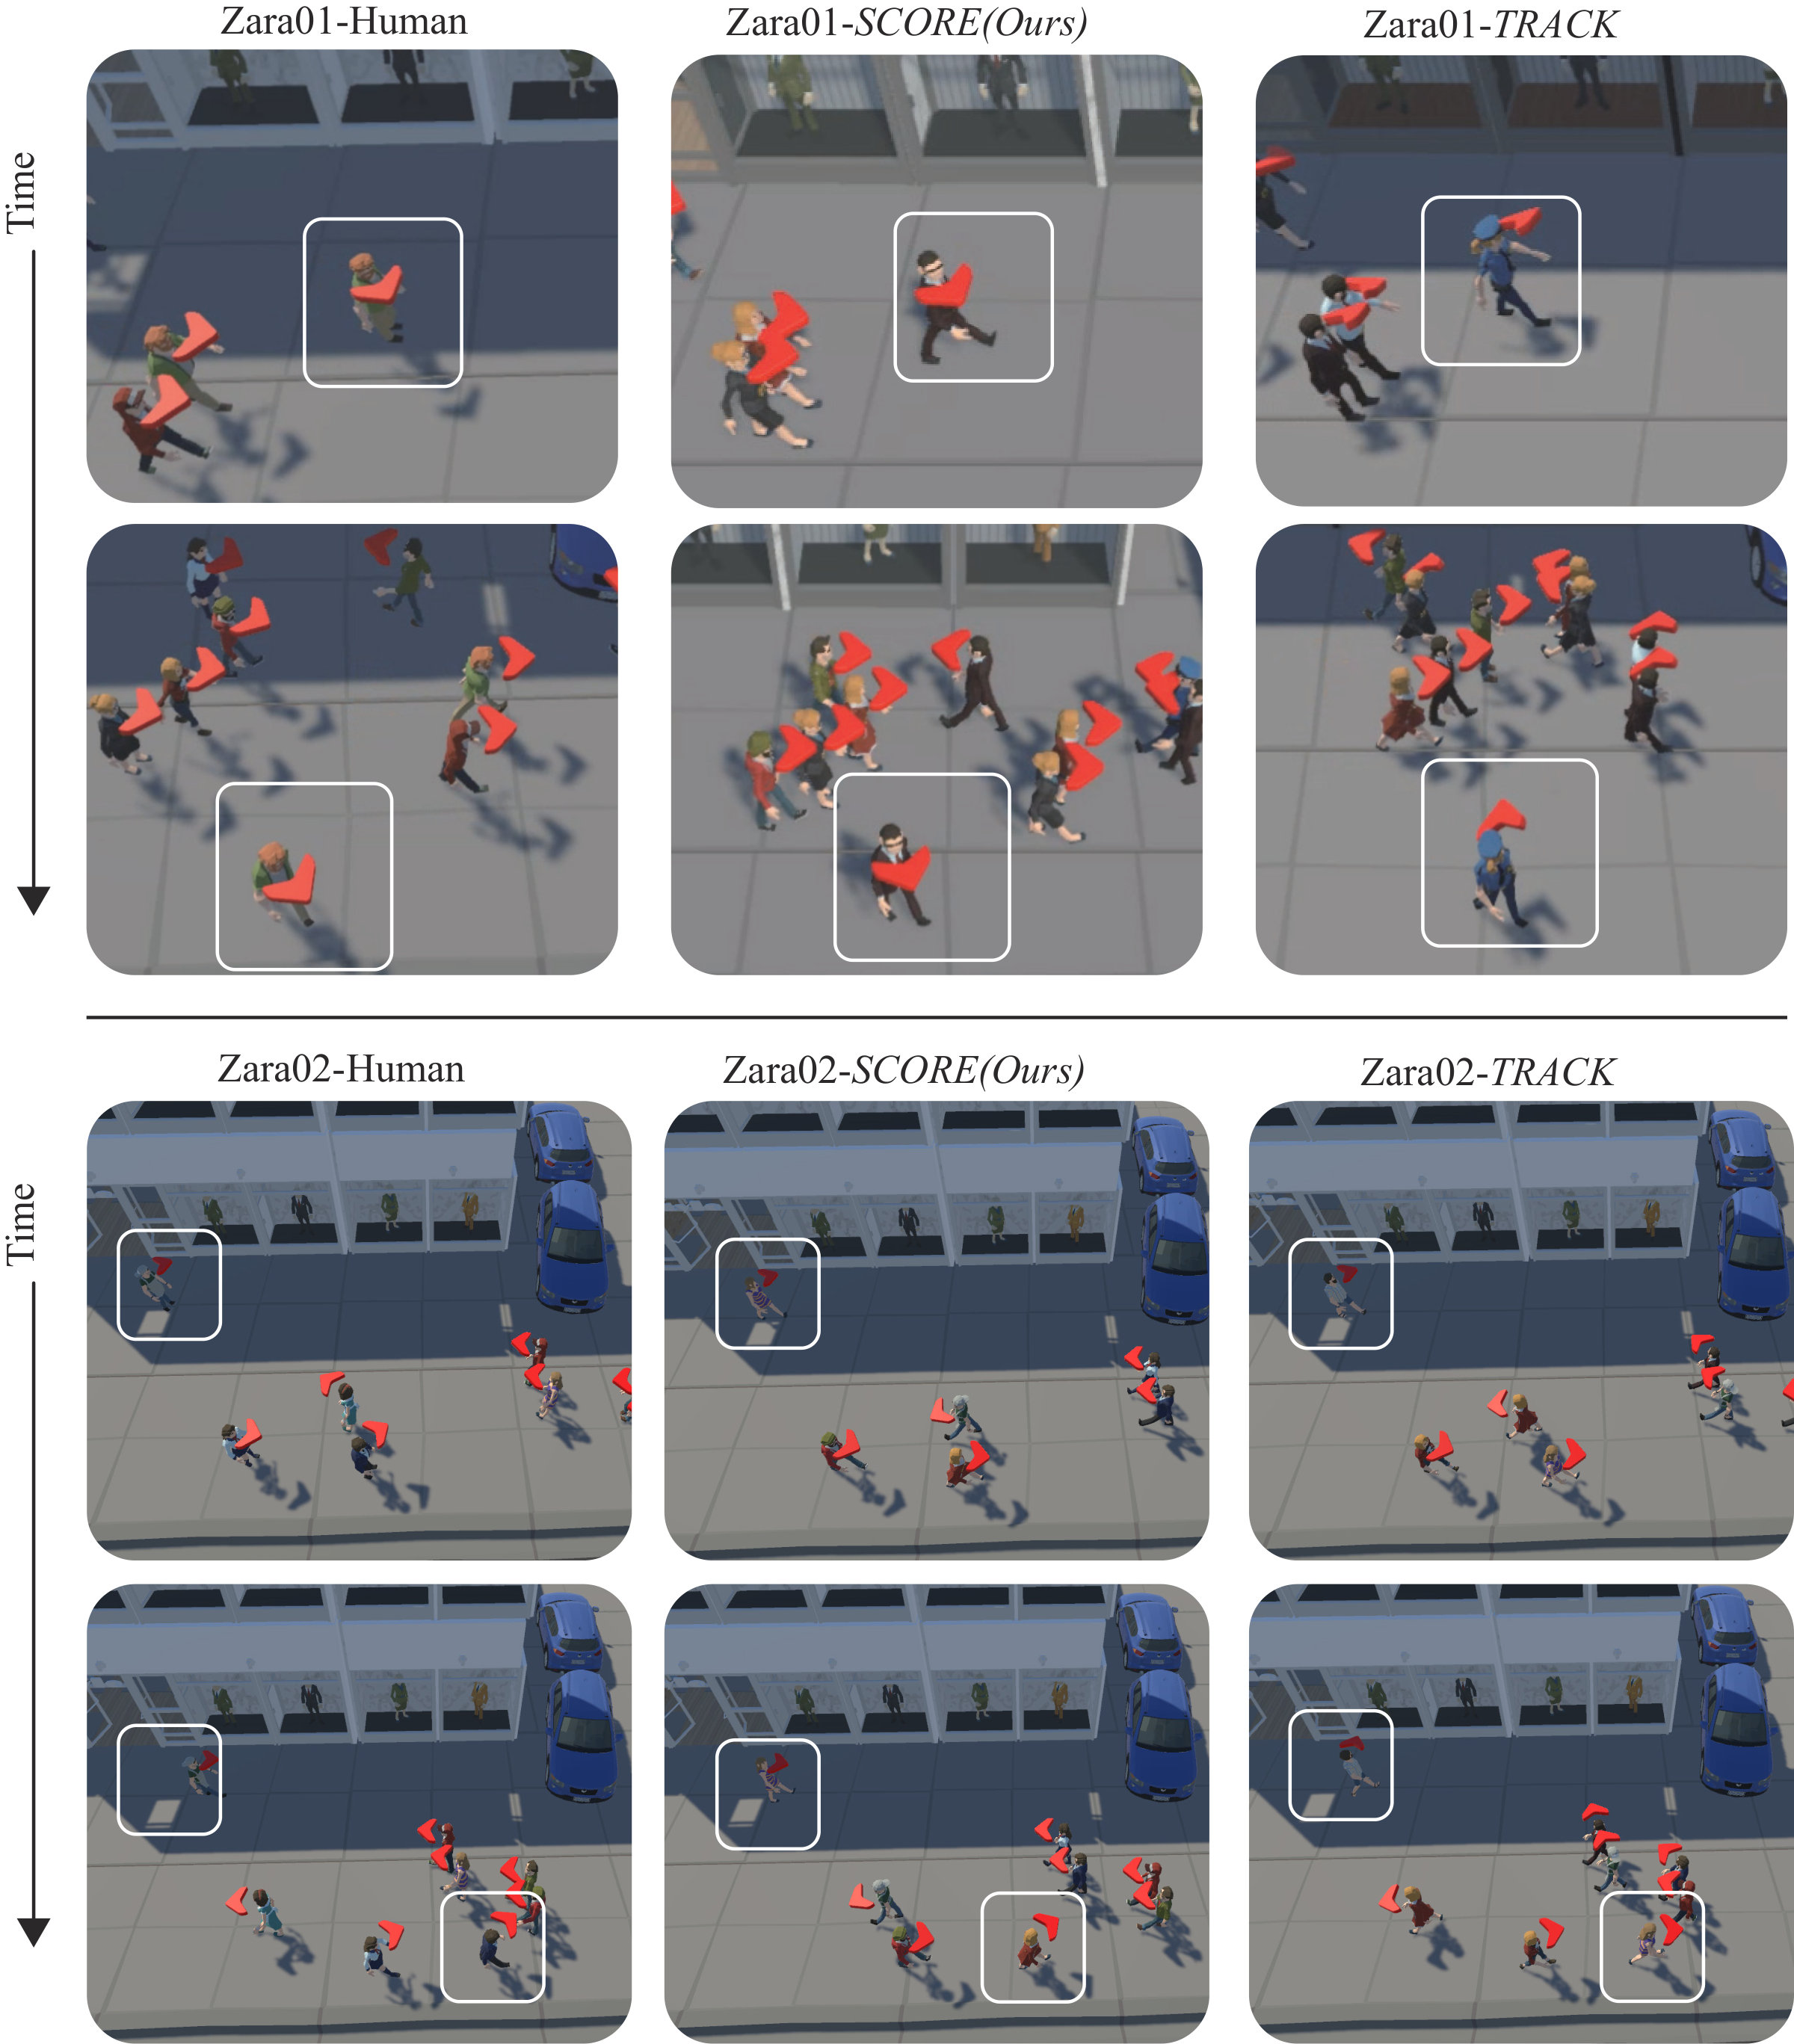
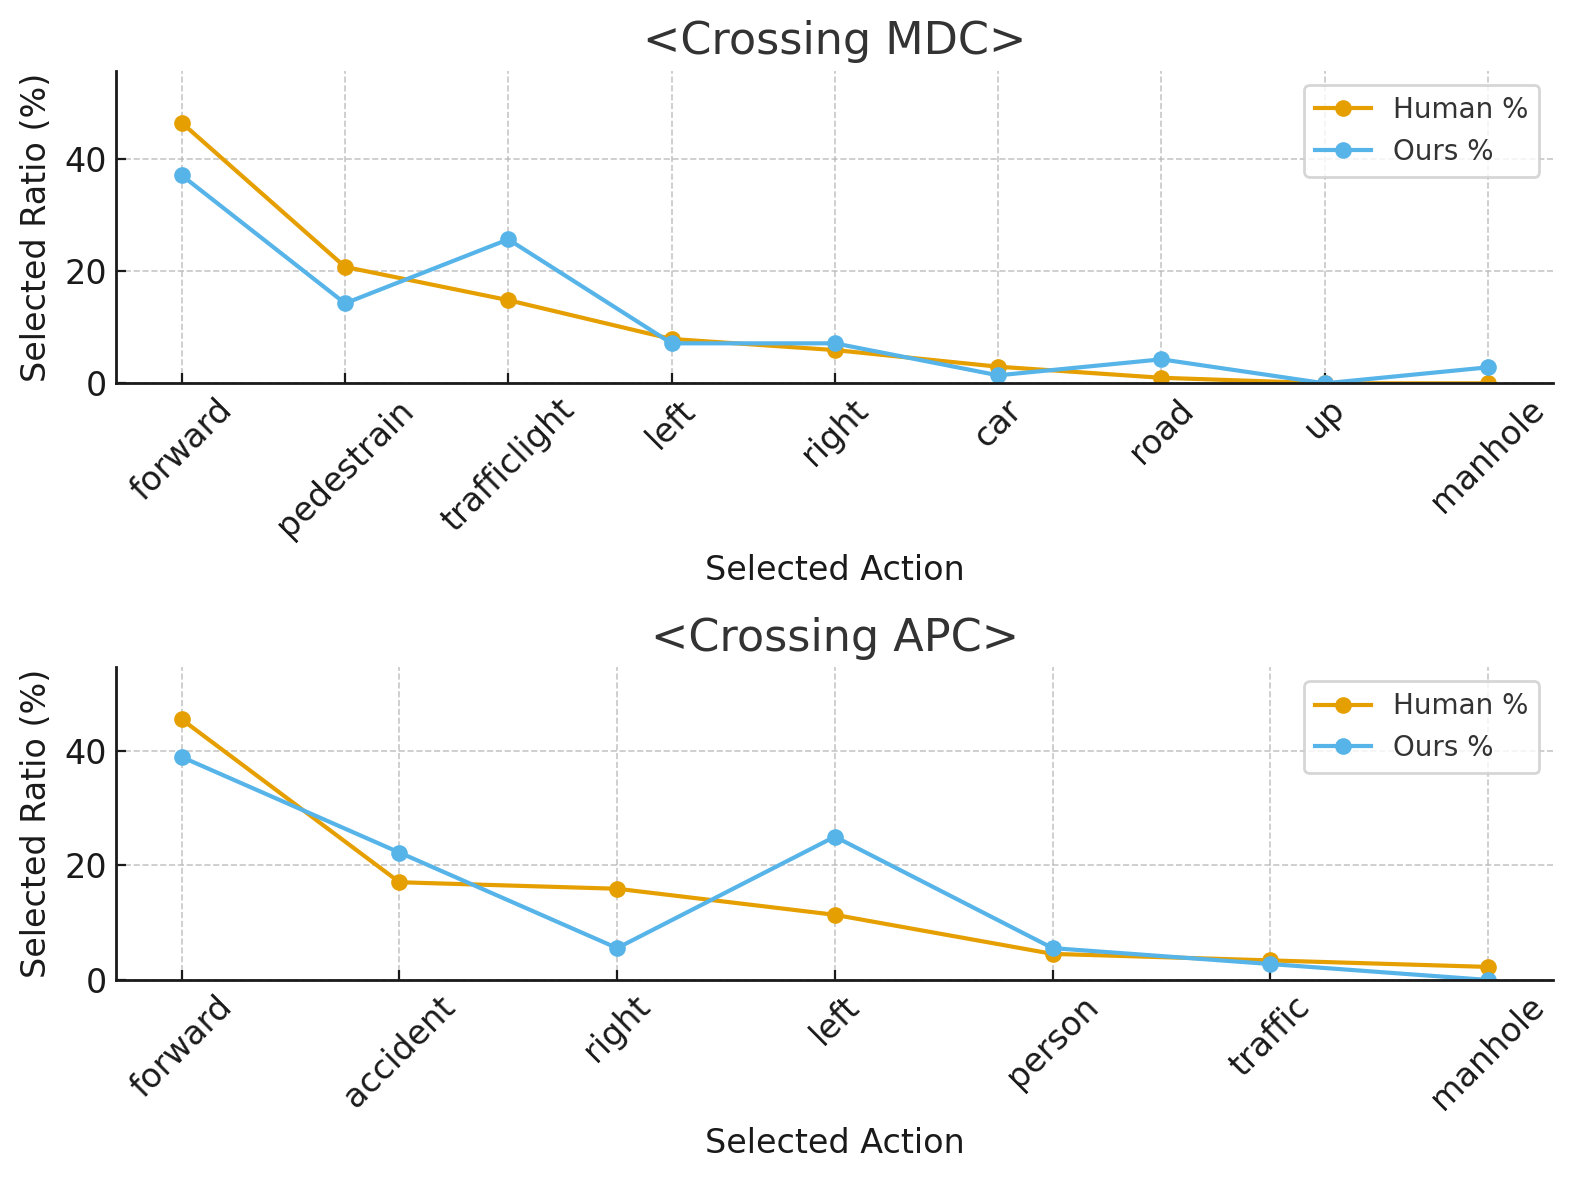
Results
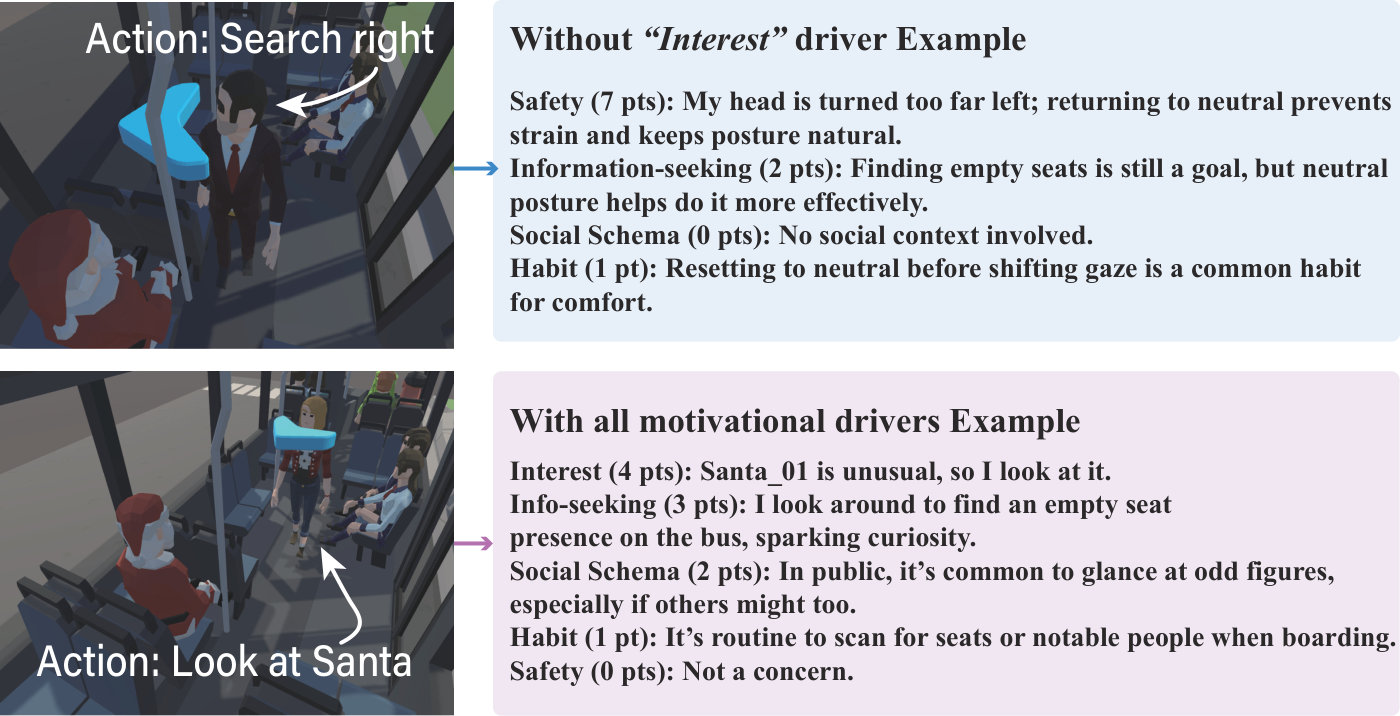
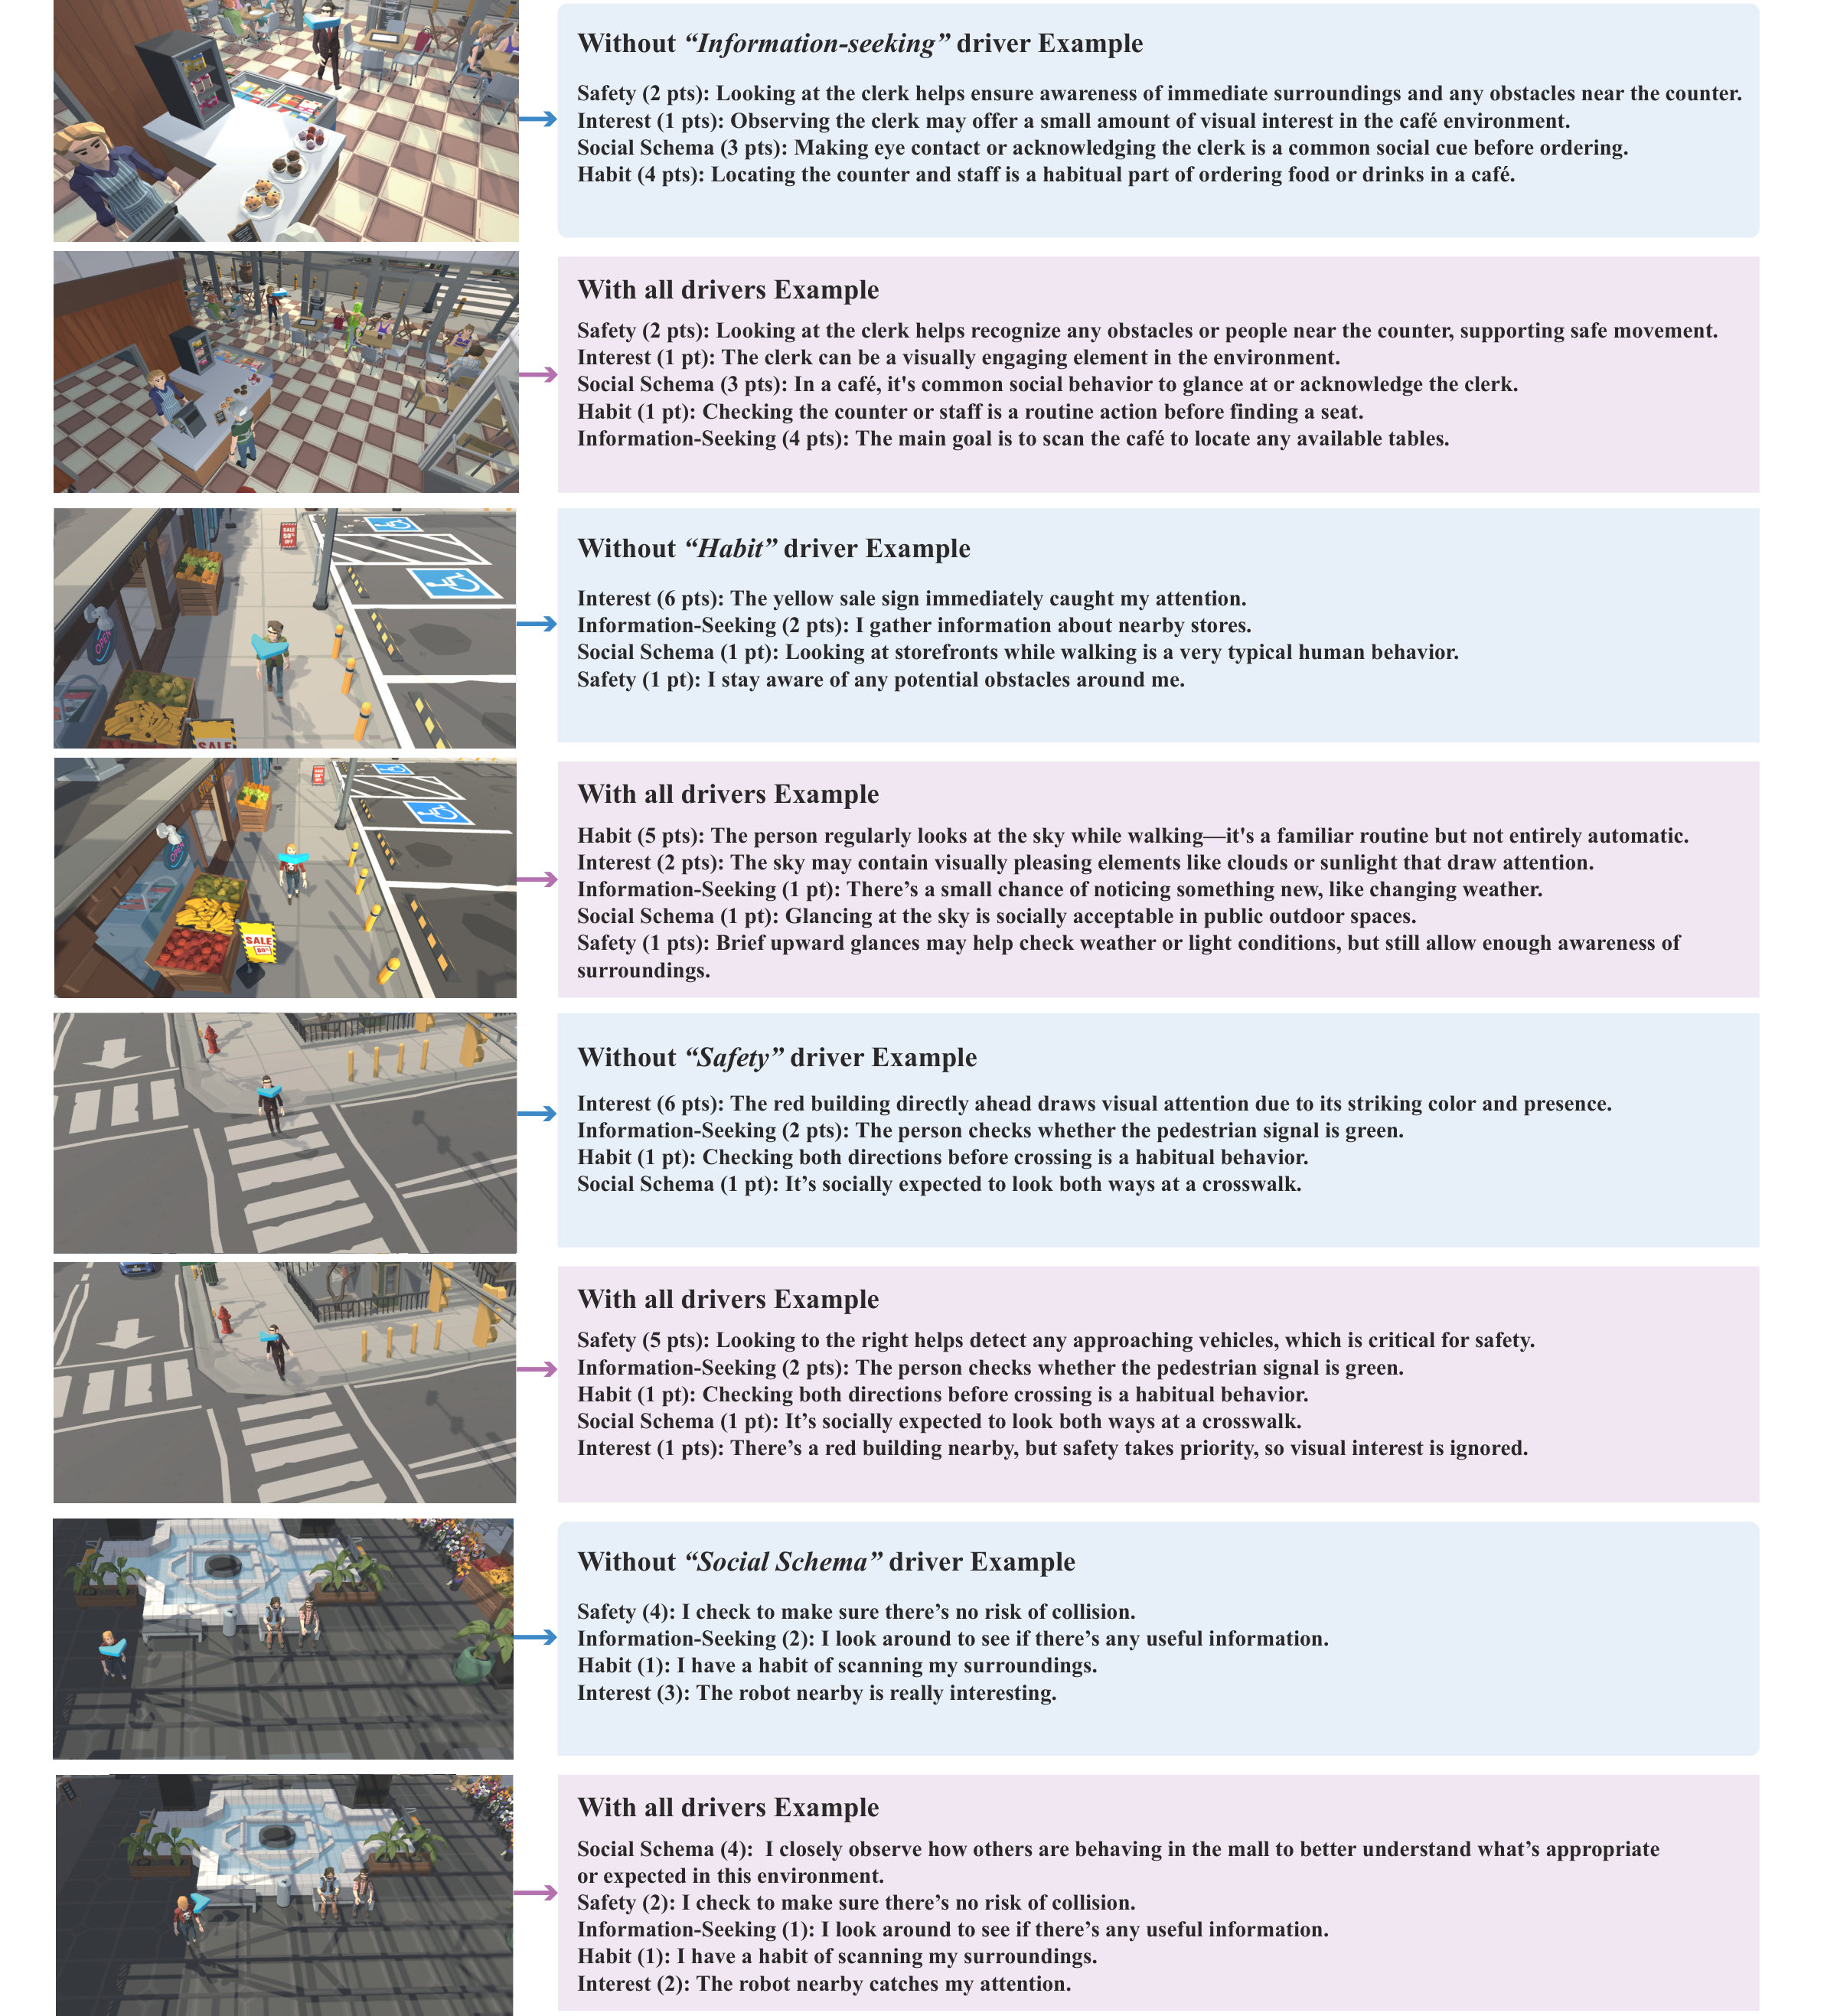
Removing a driver changes the reasoning
BibTeX
@inproceedings{hwang2025score,
  title     = {How Does a Virtual Agent Decide Where to Look? Symbolic Cognitive Reasoning for Embodied Head Rotation},
  author    = {Hwang, Juyeong and Hong, Seong-Eun and Seon, JaeYoung and Kang, HyeongYeop},
  booktitle = {SIGGRAPH Asia 2025 Conference Papers},
  year      = {2025}
}